LangChain Advisers Shankar and Husain Link LLM Failure to Data Neglect
LangChain
Building reliable AI agents requires treating LLM judges as classic, imbalanced machine learning classifiers rather than trusting unvalidated, arbitrary scoring rubrics.
AI-assisted summary of Getting Evals Right for LLM Applications | Interrupt 26 — original source. Check the original for full context.
Source published:
Key ideas
- Generic LLM metrics like 'helpfulness' or 'hallucination' are too ambiguous and context-dependent; teams must replace them with domain-specific failure categories derived directly from trace analysis. (3:28)
- LLM judges should be treated as imperfect classifiers on imbalanced datasets, requiring train/dev/test splits and evaluation via precision and recall rather than raw accuracy. (7:03)
- Continuous scoring scales such as 1-to-5 or 1-to-100 create uninterpretable metrics and should be converted into targeted binary pass/fail checks. (10:13)
- Predefined evaluation rubrics routinely suffer from criteria drift because human reviewers only discover true edge cases and failure modes when inspecting actual production outputs. (12:00)
Detailed notes
## Background Published on YouTube by LangChain on June 12, 2026, from the Interrupt agent conference, this presentation features Shreya Shankar and Hamel Husain. Drawing from their experience teaching evals to over 4,500 practitioners across dozens of companies, the talk outlines five prevalent mistakes in evaluating LLM applications and demonstrates how adopting a data scientist's mindset resolves them.
## TL;DR Husain and Shankar argue that AI engineering has regressed into unrigorous, 'vibes-based' evaluation and that building effective agent harnesses fundamentally requires classic data science disciplines. They deconstruct five widespread industry traps: relying on ambiguous off-the-shelf metrics, uncritically trusting unvalidated LLM judges, poor experimental design with naive synthetic data and continuous scoring scales, delegating labeling to non-experts while ignoring criteria drift, and attempting to fully automate evaluations. To fix these issues, they advocate for hands-on exploratory data analysis using custom trace interfaces, reframing LLM judges as imperfect binary classifiers with train/dev/test splits, generating synthetic scenarios across explicit combinatorial dimensions, and continually inspecting raw data.
## Atmosphere & style The session is lively, candid, and direct, characterized by the natural back-and-forth rapport between Husain and Shankar as they alternate between diagnosing industry bad habits and prescribing practical engineering solutions. Infused with wry humor, relatable memes, and sharp critiques of shortcuts like 1-to-100 scales and blind prompting, the talk feels like a field-tested wake-up call for AI practitioners. Rather than abstract academic theory, it carries the urgent, grounded energy of seasoned mentors urging builders to drop the hype and return to empirical fundamentals.
## Bulletin - [03:28](https://www.youtube.com/watch?v=QDQT99csHJQ&t=208s) Generic LLM metrics like 'helpfulness' or 'hallucination' are too ambiguous and context-dependent; teams must replace them with domain-specific failure categories derived directly from trace analysis. - [07:03](https://www.youtube.com/watch?v=QDQT99csHJQ&t=423s) LLM judges should be treated as imperfect classifiers on imbalanced datasets, requiring train/dev/test splits and evaluation via precision and recall rather than raw accuracy. - [10:13](https://www.youtube.com/watch?v=QDQT99csHJQ&t=613s) Continuous scoring scales such as 1-to-5 or 1-to-100 create uninterpretable metrics and should be converted into targeted binary pass/fail checks. - [12:00](https://www.youtube.com/watch?v=QDQT99csHJQ&t=720s) Predefined evaluation rubrics routinely suffer from criteria drift because human reviewers only discover true edge cases and failure modes when inspecting actual production outputs.
## Key takeaways - [00:06](https://www.youtube.com/watch?v=QDQT99csHJQ&t=6s) The evaluation harness popularized by modern agent architectures is fundamentally grounded in traditional data science practices, encompassing logs, metrics, and traces. - [01:27](https://www.youtube.com/watch?v=QDQT99csHJQ&t=87s) Modern AI engineering has regressed toward intuition and vibes-based evaluation compared to the rigorous data science and machine learning practices of four years ago. - [03:28](https://www.youtube.com/watch?v=QDQT99csHJQ&t=208s) Off-the-shelf, generic evaluation metrics fail because abstract concepts like hallucination require completely different operational definitions depending on the product domain. - [04:47](https://www.youtube.com/watch?v=QDQT99csHJQ&t=287s) Building lightweight custom UIs using AI coding tools enables practitioners and product managers to step through traces and uncover concrete application failure modes. - [06:04](https://www.youtube.com/watch?v=QDQT99csHJQ&t=364s) Deploying LLM judges without validating them against annotated ground truth leads to arbitrary Likert-scale distributions that cannot support product decisions. - [08:09](https://www.youtube.com/watch?v=QDQT99csHJQ&t=489s) LLM judging is an imbalanced classification problem where measuring raw accuracy is misleading because real failures represent only a small fraction of traces. - [08:26](https://www.youtube.com/watch?v=QDQT99csHJQ&t=506s) Synthetic data generation must be structured around hypothesized dimensions of variation and combinatorial cross-products rather than open-ended prompts. - [10:13](https://www.youtube.com/watch?v=QDQT99csHJQ&t=613s) Replacing continuous scoring scales (1-to-100) with binary classification makes evaluation metrics statistically testable and actionable for debugging. - [11:27](https://www.youtube.com/watch?v=QDQT99csHJQ&t=687s) Delegating trace labeling to general developers or outsourced workers fails because they lack the domain expertise required to judge nuanced product behavior. - [12:00](https://www.youtube.com/watch?v=QDQT99csHJQ&t=720s) Criteria drift makes upfront rubric design ineffective; evaluation standards inevitably shift as reviewers encounter unexpected real-world production cases. - [13:03](https://www.youtube.com/watch?v=QDQT99csHJQ&t=783s) Automating the entire evaluation loop with LLMs misses critical failures because models lack the tacit institutional knowledge and user expectations that human teams hold. - [13:45](https://www.youtube.com/watch?v=QDQT99csHJQ&t=825s) Tuning LLM judge prompts repeatedly against a single static dataset leads to prompt-level overfitting, requiring held-out validation sets to confirm generalization. - [15:34](https://www.youtube.com/watch?v=QDQT99csHJQ&t=934s) Every modern LLM evaluation challenge maps to established data science disciplines, including exploratory data analysis, metric design, and model validation.
## Detailed walkthrough ### [00:06](https://www.youtube.com/watch?v=QDQT99csHJQ&t=6s) The Return of the Data Scientist and Harness Engineering
Hamel Husain opens the session by welcoming the audience and declaring the theme of the talk: "the return of the data scientist." Setting the stage, he asks the audience for a show of hands regarding who has seen the recent article discussing "harness engineering." About half the audience raises their hands, prompting Husain to recommend it to anyone who has not read it yet.
Husain explains the premise of the article: a team at OpenAI ran autonomous agents over several months to construct substantial internal software. Crucial to their success was an evaluation "harness" designed to keep the agents on track. Husain points out a frequent blind spot in how software practitioners interpret this concept: > “And so when people hear harness, they usually think about specifications and unit tests, but one detail that's really important to look at is, okay, the harness also contains logs, metrics, and traces.”
This encompasses the complete observability stack. Husain states his core thesis directly: > “And what I'm here to convince you of today is that the harness is data science, or at least a big part of it is data science.”
```mermaid flowchart TD accTitle: The Harness Engineering Observability Stack accDescr: Diagram illustrating how logs, metrics, and traces feed into data science practices. subgraph S1["Traditional View"] A["Specifications"] B["Unit Tests"] end subgraph S2["Observability Stack"] C["Logs"] D["Metrics"] E["Traces"] end subgraph S3["The Reality"] F["Data Science Foundation"] end S1 --> F S2 --> F ```
[01:27](https://www.youtube.com/watch?v=QDQT99csHJQ&t=87s) ML Engineering Four Years Ago vs. Vibes-Based AI Engineering Today
Taking a step back, Husain reflects on how the discipline arrived at its current predicament by comparing traditional machine learning engineering from four years ago with modern AI engineering practices. Four years ago, ML practitioners meticulously analyzed their data, produced visualizations, diligently aligned model predictions with human labels, selected the precise tool for each specific problem, and took great care to craft metrics tightly connected to actual business objectives.
In contrast, Husain observes that current AI engineering has regressed in critical ways, relying on intuition and shortcuts rather than rigorous evaluation: > “AI engineering today feels like we've taken a bit of a step back in some places. So now, a lot of times, we're just using vibes to know if we're doing the right thing.”
Engineers often resort to asking a model—sometimes an external model, sometimes the very same model that generated the text—whether it did a good job. Furthermore, metric design has been hollowed out; teams routinely instruct an LLM to assign an arbitrary score from 1 to 100 or blindly import off-the-shelf metrics packages without understanding their mechanics. Husain diagnoses the underlying cause: engineers frequently fear what they do not understand, causing core data science competencies—specifically evaluations and retrieval—to be repeatedly dismissed and revived. Having taught evals to more than 4,500 people across dozens of companies, Husain notes that organizations consistently fall into identical traps, before passing the presentation to Shreya Shankar to detail the specific failure modes.
[03:28](https://www.youtube.com/watch?v=QDQT99csHJQ&t=208s) Mistake 1: Relying on Generic, Off-the-Shelf Metrics
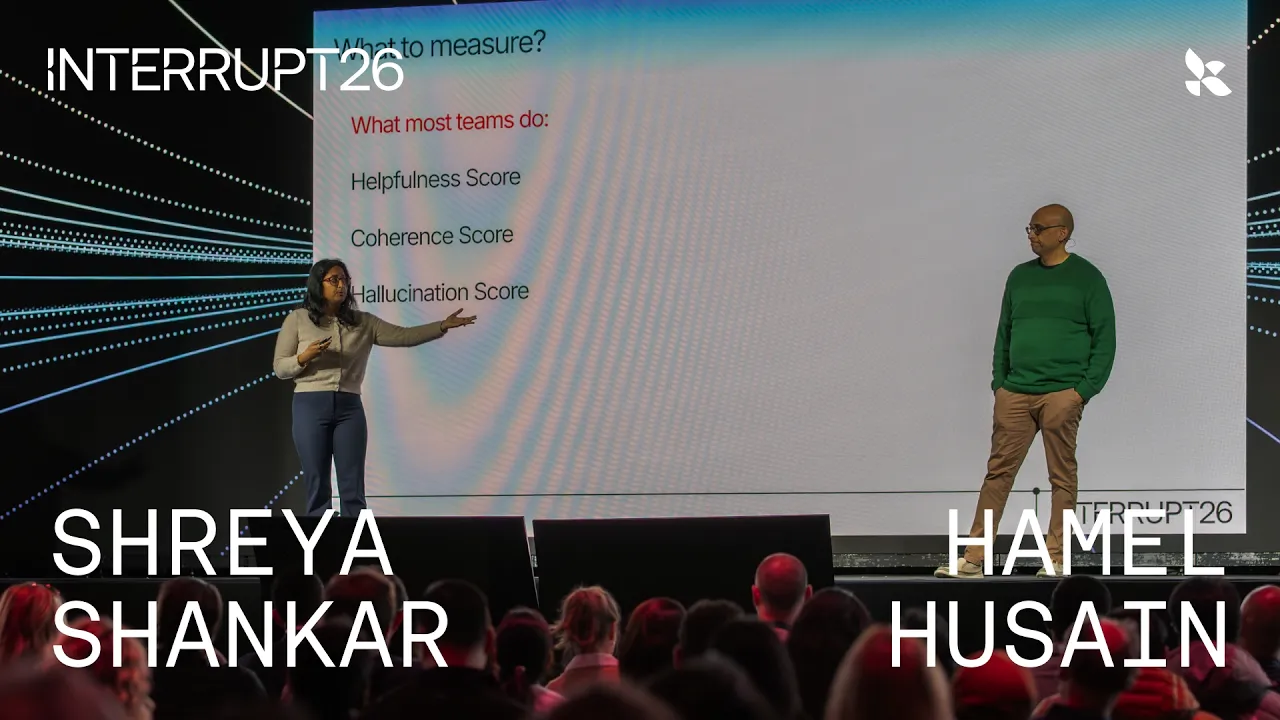
Shreya Shankar takes over to examine five critical mistakes practitioners make when building evals, framing the fixes through the lens of a data scientist. The first major pitfall is reaching for off-the-shelf, generic metrics to gauge agent accuracy or alignment: > “So the first one is kind of using metrics, what we call generic metrics or off-the-shelf metrics to measure the accuracy or alignment of your agents.”
While using generic operational metrics makes sense for traditional software—where measures like latency and uptime apply universally across applications—AI applications demand a bespoke approach. Off-the-shelf AI metrics typically revolve around abstract concepts such as "helpfulness," "coherence," or "hallucination." While these sound critical, Shankar points out that they suffer from two major flaws: 1. They are fundamentally ambiguous, making it near impossible to define what they objectively mean in practice. 2. They are deeply context-dependent. A hallucination in a healthcare application built by Husain requires an entirely different operational definition, different tools, and different data than a hallucination in a legal application built by Shankar. Evaluating both using a single off-the-shelf metric is ineffective.
[04:47](https://www.youtube.com/watch?v=QDQT99csHJQ&t=287s) Fixing Mistake 1: Exploratory Data Analysis and Custom Trace Interfaces
To break away from generic metrics, Shankar urges teams to act like data scientists by performing exploratory data analysis (EDA): directly inspecting the data, determining where the system breaks, and assigning concrete names to application-specific failure modes.
Rather than relying on static logs, Shankar highlights the value of using AI-assisted coding tools like Cursor, Claude Code, or Codex to quickly build custom user interfaces for inspecting traces. Practitioners can step through an agent's trace message by message, roleplaying as the end user, and work alongside product managers to identify where execution goes off the rails. Teams can record freeform open notes about mistakes, and as these notes accumulate, cluster them into bespoke failure categories.
Shankar illustrates this with an example from an automated real estate scheduling assistant: rather than tracking an abstract "hallucination" score, the team identified a precise, domain-specific failure mode—the agent was actively rescheduling tours when no open slots existed by hallucinating available appointment times. Shankar reinforces their core motto: > “Hamel and I always say, look at your data. And this is exactly what we mean by look at your data. It's not just, oh, look at it and don't say or think or do anything about it. It's build your own interfaces and try to find failure modes and try to do this at scale.”
```mermaid flowchart TD accTitle: Custom Interface Workflow for Failure Analysis accDescr: Step-by-step process of using custom tools to identify and categorize domain failure modes. A["Agent Execution Traces"] --> B["Build Custom UI<br/>(Cursor / Claude Code / Codex)"] B --> C["Read Messages Step-by-Step<br/>with PMs / Domain Experts"] C --> D["Write Open Exploratory Notes"] D --> E["Cluster into Bespoke Failure Modes<br/>(e.g., Fabricating Real Estate Tour Times)"] ```
[06:04](https://www.youtube.com/watch?v=QDQT99csHJQ&t=364s) Mistake 2: Blindly Trusting LLM Judges
The second widespread failure mode is using an LLM judge without verifying whether the judge itself is accurate or reliable. Shankar clarifies her stance on model-based judging: > “So I'm not saying that using LLM judges are bad. I'm saying that using LLM judges kind of blindly without validating your validators is bad.”
In standard industry practice, a team discovers a failure mode and immediately prompts an LLM to evaluate traces on a 1-to-5 scale. They plot a histogram of the resulting scores and attempt to make executive product and business decisions based on the distribution. Shankar warns that these arbitrary Likert-scale outputs are neither trustworthy nor translatable into actionable product insights.
[07:03](https://www.youtube.com/watch?v=QDQT99csHJQ&t=423s) Fixing Mistake 2: Treating LLM Judges as Imperfect ML Classifiers
A data scientist resolves this by framing the LLM judge as an imperfect machine learning classifier. Rather than relying on unchecked prompt outputs, practitioners should benchmark and develop the judge with the same rigor applied to classical machine learning: - Assemble an annotated dataset of traces containing confirmed examples of the specific failure mode. - Partition the labeled data into strict training, development (dev), and test splits. - Iterate on the judge prompt and model choice against the train and dev splits, validating that performance generalizes cleanly to the held-out test split without overfitting alignment.
Shankar emphasizes that LLM evaluation is fundamentally an imbalanced classification problem: > “And in many classification tasks, interestingly, LLM judging is often an imbalanced classification task, which is a fancy way, it's a lot of jargon for saying that only a small fraction of the trace set is a failure or a failure mode.”
Because failures represent only a tiny fraction of total traces, reporting raw accuracy is misleading—a judge that marks every trace as a success could trivially show 98% accuracy while missing every real failure. Consequently, teams must measure alignment using imbalanced classification metrics: - Precision - Recall - False positive rates - False negative rates
[08:26](https://www.youtube.com/watch?v=QDQT99csHJQ&t=506s) Mistake 3: Poor Experimental Design and Naive Synthetic Data
The third pitfall centers on flawed experimental design, particularly around synthetic data generation and scoring scale design. While synthetic data generation is valuable, naive implementations produce uniform, low-utility data. When teams ask an LLM with an unconstrained prompt like *"give me five generic questions"* to test a document question-answering bot, the generated traces collapse into homogeneous patterns lacking real-world variation.
To fix synthetic data generation, Shankar advises treating it as a structured experimental process where LLMs perform only constrained sub-tasks: 1. **Hypothesize dimensions of variation:** Inspect genuine application traces to determine how real user inputs vary across at least three distinct dimensions (such as user persona, ranging from complete novices to power users). 2. **Generate values per dimension:** Use LLMs to generate realistic, diverse variations across each individual dimension independently. 3. **Take the combinatorial cross-product:** Combine the generated dimensions across one another to construct diverse evaluation scenarios. 4. **Audit for quality:** Manually review the resulting synthetic suite to confirm structural diversity and data fidelity before deploying it into evals.
[10:13](https://www.youtube.com/watch?v=QDQT99csHJQ&t=613s) Fixing Metric Design: Replacing Continuous Scales with Binary Classifications
Turning to the metric design aspect of experimental design, Shankar explains that scoring traces across wide spectrums like 1-to-5 or 1-to-100 creates uninterpretable numbers that cannot guide engineering decisions. When a system scores an 82, teams cannot identify what broke or how to patch the underlying prompt or pipeline.
The data science solution is radical simplification: > “We'll try to make things a binary classification problem. We're trying to ask the judge for whether something fails or not, a binary classification problem, rather than one to 100 or one to five scoring for something like failure.”
By converting evaluations into targeted binary checks—determining definitively whether a specific, concrete failure mode occurred or did not occur—teams make metrics immediately interpretable, mathematically testable via classification statistics, and actionable for driving product iterations.
[10:55](https://www.youtube.com/watch?v=QDQT99csHJQ&t=655s) Aligning LLM Judges on Binary Tasks
Shreya Shankar emphasizes that aligning an LLM judge is an iterative process that cannot be solved in a single prompt attempt. Engineering teams constantly struggle with this step, and Shankar admits that even experienced practitioners run into the same barrier immediately: “Like we can never write a good LLM judge prompt on the first time.” Instead of expecting an out-of-the-box prompt to evaluate nuanced output accurately, teams must drastically simplify what they ask the model to do.
The most effective technique to overcome this difficulty is narrowing the judge's responsibility to strictly binary outcomes—such as deciding whether an output clearly passes or fails a single criterion—rather than grading on a broad or subjective spectrum. Once the task is scoped to a binary classification problem, engineers must hand-label a substantial volume of data themselves so they have a reliable ground-truth baseline against which to measure the judge's statistical alignment.
[11:27](https://www.youtube.com/watch?v=QDQT99csHJQ&t=687s) Mistake 4: Wrong Annotators and Criteria Drift
Passing the presentation back to Hamel Husain, the talk turns to a widespread human failure mode: delegating data annotation to people who lack the domain expertise required to evaluate system behavior. Husain observes that despite hearing repeatedly about the importance of inspecting data, teams consistently try to bypass the chore by outsourcing it or handing it off to the developers who wrote the application. Husain warns that this creates deeply flawed evaluation signals: “And unless you're building a coding app, it's kind of a bad idea, 'cause often those people don't have the domain expertise in whatever you're building or the problem you have.” Approaching evals like a rigorous data scientist requires skepticism toward both the labels and the annotators themselves; teams must confirm who is labeling, validate their domain qualifications, and audit the resulting annotations directly to catch unanticipated failure modes.
A primary reason hands-on inspection cannot be bypassed is criteria drift, a behavioral phenomenon documented in the research paper *Who Validates the Validators?*, co-authored by Shankar. When teams attempt to write an evaluation rubric in the abstract before viewing concrete system outputs, their expectations inevitably change the moment real data is placed in front of them. As Husain explains: “This idea that you're going to specify a rubric up front, and that's enough, is really problematic.” Rubrics written in isolation fall apart because practitioners discover edge cases, ambiguous language, and unexpected user intents only when forced to sit down and read actual production traces.
[13:03](https://www.youtube.com/watch?v=QDQT99csHJQ&t=783s) Mistake 5: Automating Too Much with LLMs
Teams frequently ask whether the entire evaluation loop can simply be handed over to a foundation model like Claude to avoid manual auditing altogether. Husain dismisses this as wishful thinking, explaining that while an LLM can catch obvious crashes, blatant formatting errors, or surface-level breakages, it has no window into domain-specific business expectations: “Like, Claude can't read your mind.”
Automated judges fail to detect critical product failures because they lack the implicit institutional knowledge and nuanced user expectations that human engineers carry. Uncovering why a response fails a user requires externalizing that tacit product context into explicit tests, rubrics, and data checks—work that no generic model prompt can invent on its own.
[13:45](https://www.youtube.com/watch?v=QDQT99csHJQ&t=825s) Rapid-Fire Pitfalls: ROUGE/BLEU, Raw JSON, and Overfitting
Husain runs through a rapid-fire catalog of recurring mistakes that derail production evaluation suites:
- **Misusing legacy NLP similarity scores:** Off-the-shelf evaluation frameworks frequently ship with classical metrics like ROUGE or BLEU enabled by default on dashboards, even though word-overlap metrics rarely correlate with actual response quality or semantic correctness in modern generative applications. - **Vague judge prompts:** Prompting an LLM judge with broad questions like "Is this helpful?" yields noisy, inconsistent judgments because the prompt is disconnected from the concrete failure modes of the specific product. - **Forcing annotators to read raw JSON:** Making human reviewers comb through unparsed JSON payloads adds unnecessary cognitive friction that degrades label quality; teams should instead build lightweight, custom annotation interfaces that make reviewing traces fast and delightful. - **Uncalibrated judge metrics:** Reporting scores from an automated judge without first measuring its statistical alignment against verified human labels turns metrics into pure guesswork. - **Ignoring criteria drift:** Failing to monitor how internal evaluation standards evolve over time as reviewers encounter new edge cases. - **Overfitting judges to development data:** Iteratively tuning a judge prompt against a single static dataset leads to prompt-level overfitting, identical to hill-climbing on training data in classical machine learning; teams must maintain held-out validation sets to confirm their judges generalize to unseen outputs. - **Poor data sampling and vanity metrics:** Sampling data carelessly or plastering dashboards with uncalibrated metrics that fail to provide real signal wastes engineering bandwidth.
Regarding the risk of tuning prompts without proper holdout sets, Husain stresses: “You need to set aside some data and make sure that your evals are generalizing.”
[15:34](https://www.youtube.com/watch?v=QDQT99csHJQ&t=934s) The Data Science Corollary and Final Takeaway
Stepping back from individual mistakes, Husain frames modern LLM evaluation not as an entirely new discipline, but as the natural resurgence of foundational data science practices. Every major failure mode in building LLM evals maps directly to a well-established data science skill: error analysis on model traces is equivalent to exploratory data analysis (EDA); scoping narrow pass/fail criteria is classic metric design; and measuring judge-to-human agreement is standard model validation.
```mermaid flowchart TD accTitle: Mapping LLM Eval Tasks to Classical Data Science Disciplines accDescr: A diagram connecting LLM evaluation tasks to their corresponding data science foundational skills.
subgraph LLM_Tasks["LLM Evaluation Workflow"] T1["Trace Error Analysis"] T2["Targeted Pass/Fail Checks"] T3["Judge-to-Human Alignment"] T4["Held-Out Test Sets"] T5["Production Observability"] end
subgraph DS_Skills["Data Science Foundation"] S1["Exploratory Data Analysis (EDA)"] S2["Metric Design"] S3["Model Validation"] S4["Dataset Curation"] S5["Monitoring & Telemetry"] end
T1 --> S1 T2 --> S2 T3 --> S3 T4 --> S4 T5 --> S5 ```
Building robust AI systems requires adopting a hypothesis-driven, scientific mindset where practitioners curate representative test sets, design specific measurements, and continually validate system behavior against reality. Husain directs attendees to an open-source evaluation skills repository designed to help teams audit their evaluation pipelines for these pitfalls.
Closing out the session, Husain delivers the single non-negotiable rule of the talk: “But most importantly, if you want to come away with something from this talk, is to always look at your data.” The presentation concludes with a QR code providing attendees access to the full slide deck alongside the collection of presentation memes.
## Notable quotes > [06:04](https://www.youtube.com/watch?v=QDQT99csHJQ&t=364s) I'm not saying that using LLM judges are bad. I'm saying that using LLM judges kind of blindly without validating your validators is bad. — Shreya Shankar
> [01:27](https://www.youtube.com/watch?v=QDQT99csHJQ&t=87s) AI engineering today feels like we've taken a bit of a step back in some places. So now, a lot of times, we're just using vibes to know if we're doing the right thing. — Hamel Husain
> [11:27](https://www.youtube.com/watch?v=QDQT99csHJQ&t=687s) This idea that you're going to specify a rubric up front, and that's enough, is really problematic. — Hamel Husain
> [13:45](https://www.youtube.com/watch?v=QDQT99csHJQ&t=825s) You need to set aside some data and make sure that your evals are generalizing. — Hamel Husain
## Mentioned Hamel Husain, Shreya Shankar, OpenAI, Cursor, Claude Code, Codex, Claude, LangChain, Who Validates the Validators?, ROUGE, BLEU
## Video description Shreya Shankar and Hamel Husain have taught evals to over 4,500 people across dozens of companies, and they keep seeing the same mistakes. This talk walks through five of the most common pitfalls and how thinking like a data scientist fixes them.
At Interrupt, the agent conference by LangChain, they covered: • Why generic metrics like "helpfulness" and "hallucination" are too ambiguous to use off the shelf • How to treat LLM judges as imperfect classifiers with train/dev/test splits • Why synthetic data generation goes wrong and how to fix it • Who should actually be labeling your data • What criteria drift is and why it happens • Why fully automating evals misses the product failures that matter most
The Return of the Data Scientist | Interrupt 26 0:00 Introduction 0:38 What is the harness? Logs, metrics, and traces 1:17 The harness is data science 1:27 How we got here: ML engineering 4 years ago 2:05 AI engineering today: vibes-based evaluation 2:37 What this talk covers: evals and common mistakes 3:28 Mistake 1: using generic or off-the-shelf metrics 4:47 How to fix it: explore data, build custom interfaces 6:04 Mistake 2: blindly trusting LLM judges 7:03 Treating LLM judges like ML classifiers 8:09 LLM judges as imbalanced classification problems 8:26 Mistake 3: bad experimental design 9:04 How to fix it: systematic synthetic data generation 10:13 Bad metric design: 1-to-100 scales 10:33 How to fix it: binary classification problems 11:23 Mistake 4: wrong people labeling data 12:00 Criteria drift 13:03 Mistake 5: automating too much 13:45 Other pitfalls: ROUGE/BLEU, unhelpful judge prompts, raw JSON, uncalibrated scores 15:34 The data science corollary: EDA, metric design, model validation 16:47 Summary: always look at your data 17:00 Where to get the slides
Extra resources: • Evals skills: https://github.com/hamelsmu/evals-skills • Everything mentioned during the session: https://maven.com/parlance-labs/o/0cb2fa • Everything we shipped at Interrupt: https://www.langchain.com/blog/interr... • Meet LangSmith Engine: https://www.langchain.com/blog/introd... • About LangChain: https://www.langchain.com/
[Source](https://www.youtube.com/watch?v=QDQT99csHJQ)